 HueWalls
FLUX 3 Klein 在 Mac 上的 ComfyUI 实测
在 M4 Max Mac 上用 ComfyUI 跑 FLUX 3 Klein 的可复现记录:版本、模型文件、跑通的工作流 JSON、真实耗时和遇到的每个问题。
这是一份在 Mac 上用 ComfyUI 跑 FLUX 3 Klein 的可复现记录:确切的版本、三个模型文件、在苹果芯片上跑通的工作流 JSON、真实耗时,以及我们遇到的每一个问题。HueWalls 上的壁纸就是这样做出来的。下面所有数据都是在我们自己的机器上测的;只跑过一次或没测过的地方,我们会直接写明。
我们的环境
| 项目 | 我们用的 |
|---|---|
| 机器 | Mac,Apple M4 Max,64 GB 统一内存 |
| macOS | 15.3 |
| ComfyUI | 0.42.5(桌面版)。官方教程要求 0.41.0 及以上 |
| Python / PyTorch | 3.13.12 / 2.12.1,MPS 后端 |
| 启动参数 | --enable-assets --enable-manager,另外指定了输入、输出目录。没有 --gpu-only |
三个模型文件
三个文件都来自 Hugging Face 上需要授权的仓库 black-forest-labs/flux-3-image-klein-comfy,要先在页面上同意许可协议才能下载。权重使用 FLUX Kommunity License,商用之前请自己读一遍许可。
| 文件 | 放在 | 在我们磁盘上的大小 | 作用 |
|---|---|---|---|
flux3-image-klein-base-int8-convrot.safetensors |
ComfyUI/models/diffusion_models/ |
5.41 GiB | 图像模型 |
qwen3vl_4b_int8_convrot.safetensors |
ComfyUI/models/text_encoders/ |
4.52 GiB | 文本编码器 |
flux2-vae.safetensors |
ComfyUI/models/vae/ |
0.31 GiB | VAE |
同一个页面还列了蒸馏版模型(flux3-image-klein-int8-convrot.safetensors,4 到 16 步,CFG 1)和提示词扩写模型(qwen3.5_9b_flux3_prompt_upsampler_w4a8.safetensors),我们都没用。扩写模型就是下面第一个问题的来源。
采样设置
| 设置 | 取值 |
|---|---|
| 模型 | base 版(flux3-image-klein-base-int8-convrot) |
| 步数 | 30(官方教程对 base 版建议 50 步,我们没有对比过两者) |
| CFG | 3.5 |
| 采样器 / 调度器 | euler / simple |
| 去噪强度、批大小 | 1.0、1 |
| 负面提示词 | 空 |
| 提示词扩写 | 关闭 |
| 文本编码器加载 | CLIPLoader,type 选 flux3 |
工作流 JSON
这是在我们的 Mac 上跑通的工作流,格式是 ComfyUI 的 API 格式,也就是 /prompt 接口接收的那种。我们从官方的 Klein 模板出发,删掉了提示词扩写的节点。节点 18:17 放正向提示词,18:6 是图像尺寸,18:7 是采样设置。我们是通过 HTTP 接口来调用它的;没有测试过在 ComfyUI 界面里导入这个文件。
{
  "9": {
    "inputs": {
      "filename_prefix": "flux3",
      "images": [
        "18:8",
        0
      ]
    },
    "class_type": "SaveImage",
    "_meta": {
      "title": "保存图像"
    }
  },
  "18:17": {
    "inputs": {
      "value": ""
    },
    "class_type": "PrimitiveStringMultiline",
    "_meta": {
      "title": "字符串(多行)"
    }
  },
  "18:1": {
    "inputs": {
      "unet_name": "flux3-image-klein-base-int8-convrot.safetensors",
      "weight_dtype": "default"
    },
    "class_type": "UNETLoader",
    "_meta": {
      "title": "UNet加载器"
    }
  },
  "18:4": {
    "inputs": {
      "text": [
        "18:17",
        0
      ],
      "clip": [
        "18:2",
        0
      ]
    },
    "class_type": "CLIPTextEncode",
    "_meta": {
      "title": "Positive Prompt"
    }
  },
  "18:2": {
    "inputs": {
      "clip_name": "qwen3vl_4b_int8_convrot.safetensors",
      "type": "flux3",
      "device": "default"
    },
    "class_type": "CLIPLoader",
    "_meta": {
      "title": "加载CLIP"
    }
  },
  "18:7": {
    "inputs": {
      "seed": 1,
      "steps": 30,
      "cfg": 3.5,
      "sampler_name": "euler",
      "scheduler": "simple",
      "denoise": 1.0,
      "model": [
        "18:1",
        0
      ],
      "positive": [
        "18:4",
        0
      ],
      "negative": [
        "18:5",
        0
      ],
      "latent_image": [
        "18:6",
        0
      ]
    },
    "class_type": "KSampler",
    "_meta": {
      "title": "K采样器"
    }
  },
  "18:3": {
    "inputs": {
      "vae_name": "flux2-vae.safetensors"
    },
    "class_type": "VAELoader",
    "_meta": {
      "title": "加载VAE"
    }
  },
  "18:6": {
    "inputs": {
      "width": 1008,
      "height": 2176,
      "batch_size": 1
    },
    "class_type": "EmptyFlux2LatentImage",
    "_meta": {
      "title": "空Latent图像(Flux2)"
    }
  },
  "18:5": {
    "inputs": {
      "text": "",
      "clip": [
        "18:2",
        0
      ]
    },
    "class_type": "CLIPTextEncode",
    "_meta": {
      "title": "Negative Prompt (empty = reference default)"
    }
  },
  "18:8": {
    "inputs": {
      "samples": [
        "18:7",
        0
      ],
      "vae": [
        "18:3",
        0
      ]
    },
    "class_type": "VAEDecode",
    "_meta": {
      "title": "VAE解码"
    }
  }
}
下面是一段最小的提交脚本,提交后等待结果(把上面的 JSON 存成 flux3_klein_api.json):
import json, random, time, urllib.request

HOST = "http://127.0.0.1:8188"

def call(path, body=None):
    req = urllib.request.Request(HOST + path, data=json.dumps(body).encode() if body is not None else None,
                                 headers={"Content-Type": "application/json"})
    return json.load(urllib.request.urlopen(req, timeout=30))

wf = json.load(open("flux3_klein_api.json"))
wf["18:17"]["inputs"]["value"] = "A cozy window seat on a snowy evening, ..."   # positive prompt
wf["18:6"]["inputs"].update(width=1008, height=2176)                           # multiples of 16
wf["18:7"]["inputs"].update(seed=random.randint(1, 2**50), steps=30, cfg=3.5)
wf["9"]["inputs"]["filename_prefix"] = "flux3_demo"

pid = call("/prompt", {"prompt": wf, "client_id": "demo"})["prompt_id"]
while pid not in (hist := call("/history")):
    time.sleep(15)
print(hist[pid]["status"]["status_str"], [i["filename"] for o in hist[pid]["outputs"].values() for i in o.get("images", [])])
出一张图要多久
| 尺寸 | 图像 token 数 | 结果 | 耗时 |
|---|---|---|---|
| 1008×2176(手机) | 63 × 136 = 8,568 | 能跑 | 三次分别是 561、554、586 秒 |
| 1600×896(16:9) | 100 × 56 = 5,600 | 能跑 | 340 秒(跑了一次,就是本文的封面) |
| 1728×1088(电脑) | 108 × 68 = 7,344 | 能跑 | 约 480 秒(更早的一次) |
| 2560×1600(电脑) | 160 × 100 = 16,000 | 报 INT_MAX 错误 | 跑了 20 多分钟之后才失败(更早的一次尝试) |
所有测试都是 30 步,一次只跑一张。"图像 token 数"就是 宽 ÷ 16 × 高 ÷ 16。从这几次测试看,约 9000 个图像 token 以内能跑,16000 不行;中间的确切上限我们没有找出来。
出图效果
下面是计时测试里的三张手机尺寸结果:Give Thanks(561 秒)、Thanksgiving(554 秒)和雪夜窗边(586 秒)。两张带文字的图第一次就拼对了。
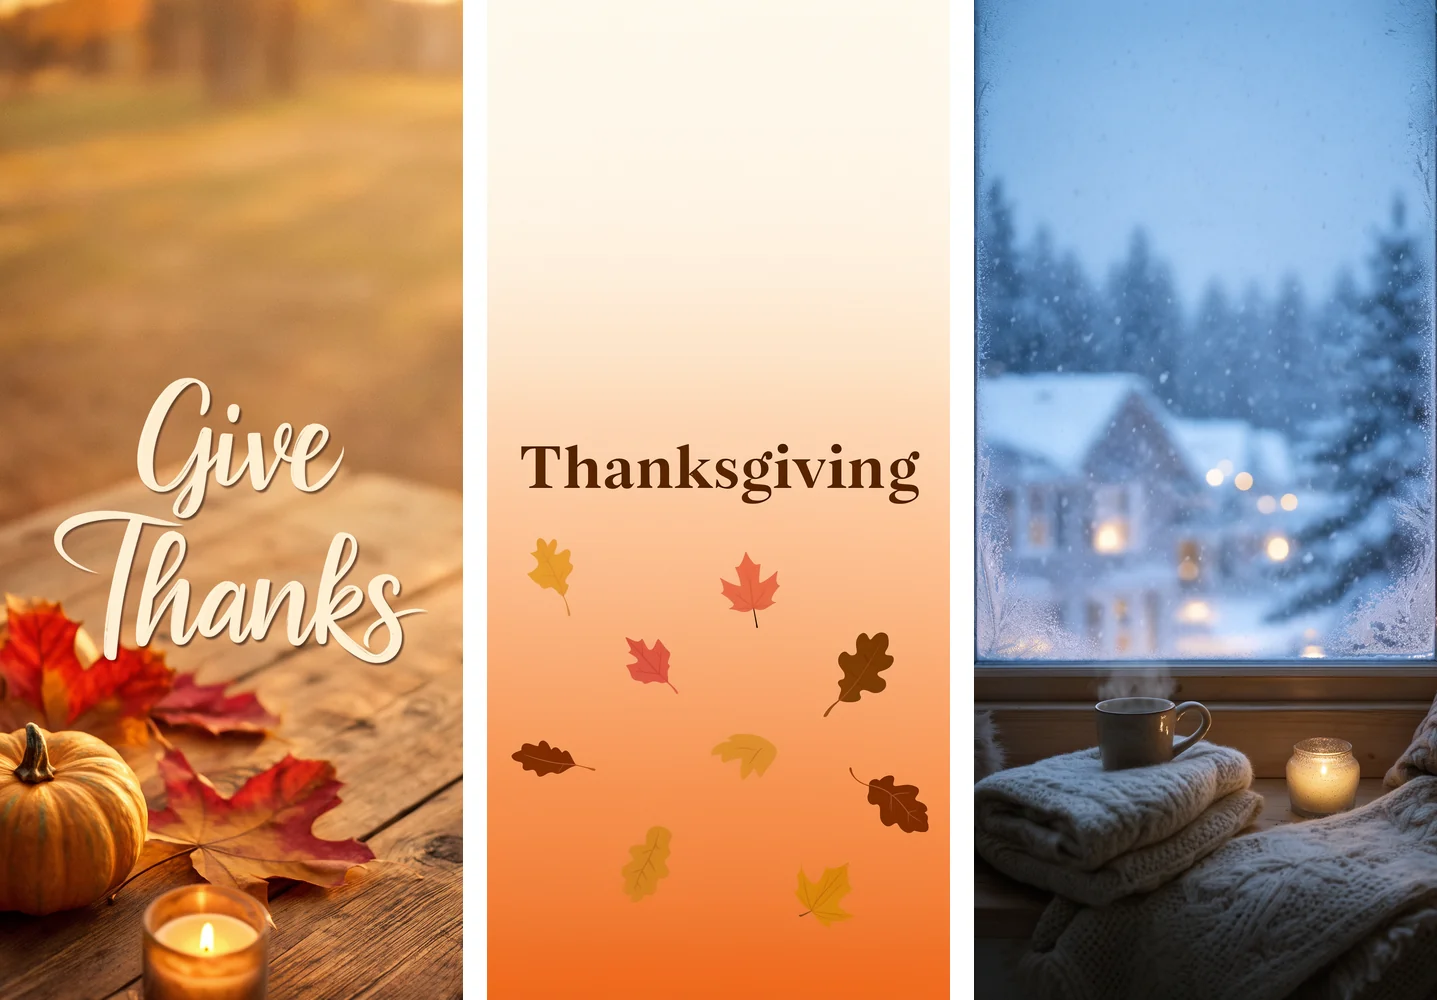
从左到右:Give Thanks、Thanksgiving、雪夜窗边。1008×2176,30 步,CFG 3.5。
再看一张 1728×1088 的电脑尺寸结果,图里有一块写着 Merry Christmas 的牌子:
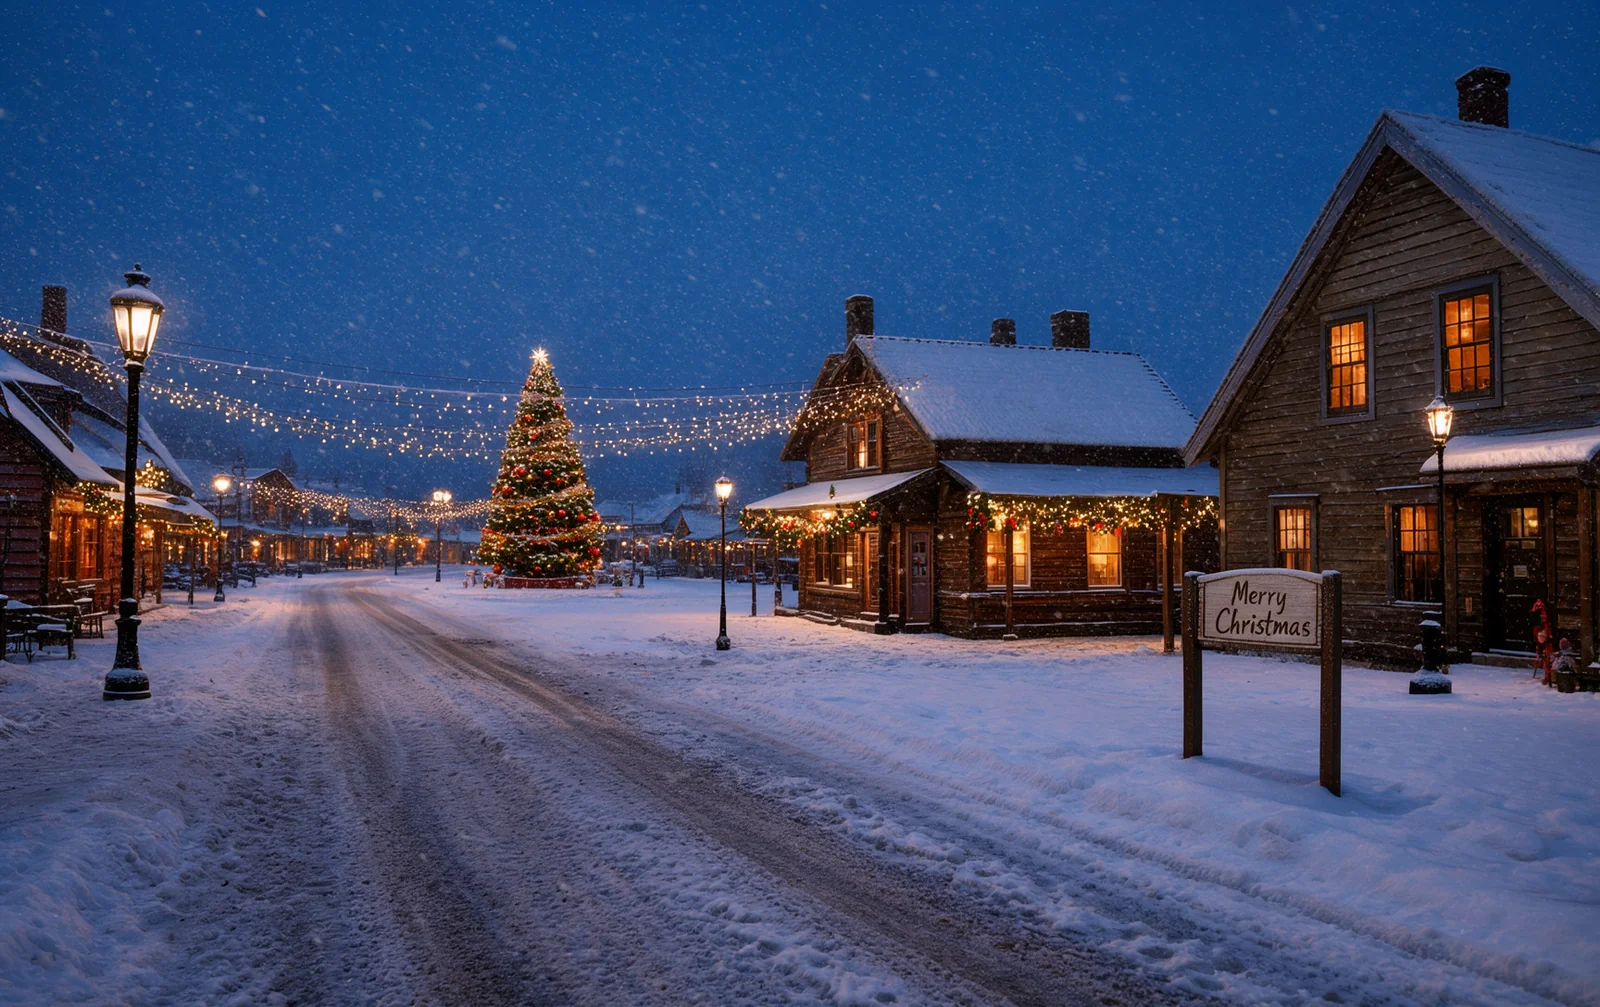
1728×1088,更早的一次测试。
| 测试 | 随机种子 | 耗时 |
|---|---|---|
| Give Thanks | 864806374791918 | 560.9 秒 |
| Thanksgiving | 283171623447621 | 554.0 秒 |
| 雪夜窗边 | 986995460342718 | 586.1 秒 |
这三次测试提交的提示词,原文如下:
A vertical photo-realistic photograph. A rustic wooden table in warm afternoon light, with a small pumpkin, a few dried maple leaves in red and orange, and a lit candle in the lower part of the frame. In the middle of the frame, elegant hand-lettered cursive text that reads the words Give Thanks, in soft cream white, large and clearly legible, with a subtle shadow. Warm golden-hour color palette, shallow depth of field, soft film grain. The top third of the frame is clean, softly blurred warm background, left empty. No people, no logos, no other text.
A vertical minimalist flat illustration. A smooth gradient background from burnt orange at the bottom to warm cream at the top. A few simple falling maple leaves and oak leaves in terracotta, mustard and deep brown, scattered across the lower two thirds. In the middle of the frame, bold clean serif text that reads the words Thanksgiving, in deep brown, large, centered, high contrast against the background. The top third of the frame is a plain, uncluttered area kept empty. No people, no logos, no other text.
A vertical photo-realistic photograph of a cozy window seat on a snowy evening: a wide wooden windowsill with a folded cream knit blanket and a steaming ceramic mug, a small candle glowing beside it. Outside the frosted glass, soft snow falls over blurred pine trees and distant warm yellow house lights. Soft diffused blue-grey twilight mixed with warm candle glow, small ice crystals on the glass corners, calm and quiet mood, shallow depth of field, film-like grain. The still life sits in the lower middle of the frame, fully inside the frame, and the top third is a clean, softly blurred snowy window area left empty. No people, no text, no logos.
我们试过的五个英文短语都拼对了:OPEN LATE、Merry Christmas、Books and Tea、Give Thanks 和 Thanksgiving。写法是在提示词里写 the words Give Thanks,不加引号。
样本很少:每个短语只试了一个种子,而且都是短文本。我们对每张图仍然会用眼睛核对拼写。
我们遇到的问题
Float8_e4m3fn not supported。 w4a8 的提示词扩写模型在苹果的 MPS 后端上会报这个错。放到 CPU 上能跑,但慢到没法用。我们把扩写节点从工作流里删掉了,所以提示词要自己写足细节:光线、材质、构图,以及画面里哪一块要留空。- 加了
--gpu-only之后同样的错误又出现。 给 ComfyUI 加--gpu-only这类全局启动参数,会让 Float8 错误回来,所以我们不动启动参数。 - 大尺寸要很久才失败。 在 MPS 上注意力张量有硬性大小上限(INT_MAX)。2560×1600 的图跑了 20 多分钟才报错。排任务之前先算一下 宽 ÷ 16 × 高 ÷ 16。
- 内存压力。 同时跑别的重任务,系统可能把 ComfyUI 杀掉。我们一次只跑一张图,机器上不跑别的重活。
我们没有测试的
- 30 步和官方对 base 版建议的 50 步的画质对比。
- 蒸馏版模型,4 到 16 步,应该会快很多。
- 其他型号的 Mac,以及小于 64 GB 的内存。
- 在 ComfyUI 界面里导入这个 JSON(我们一直是走 API 调用的)。
小结
- 一张手机尺寸的图按 10 分钟估,一次只跑一张。
- 排任务前先算 宽 ÷ 16 × 高 ÷ 16,MPS 上要控制在 9000 左右以内。
- 用 int8 文本编码器,type 选
flux3,不要动全局启动参数。 - 短而大的文字渲染得不错,但一定要核对拼写。